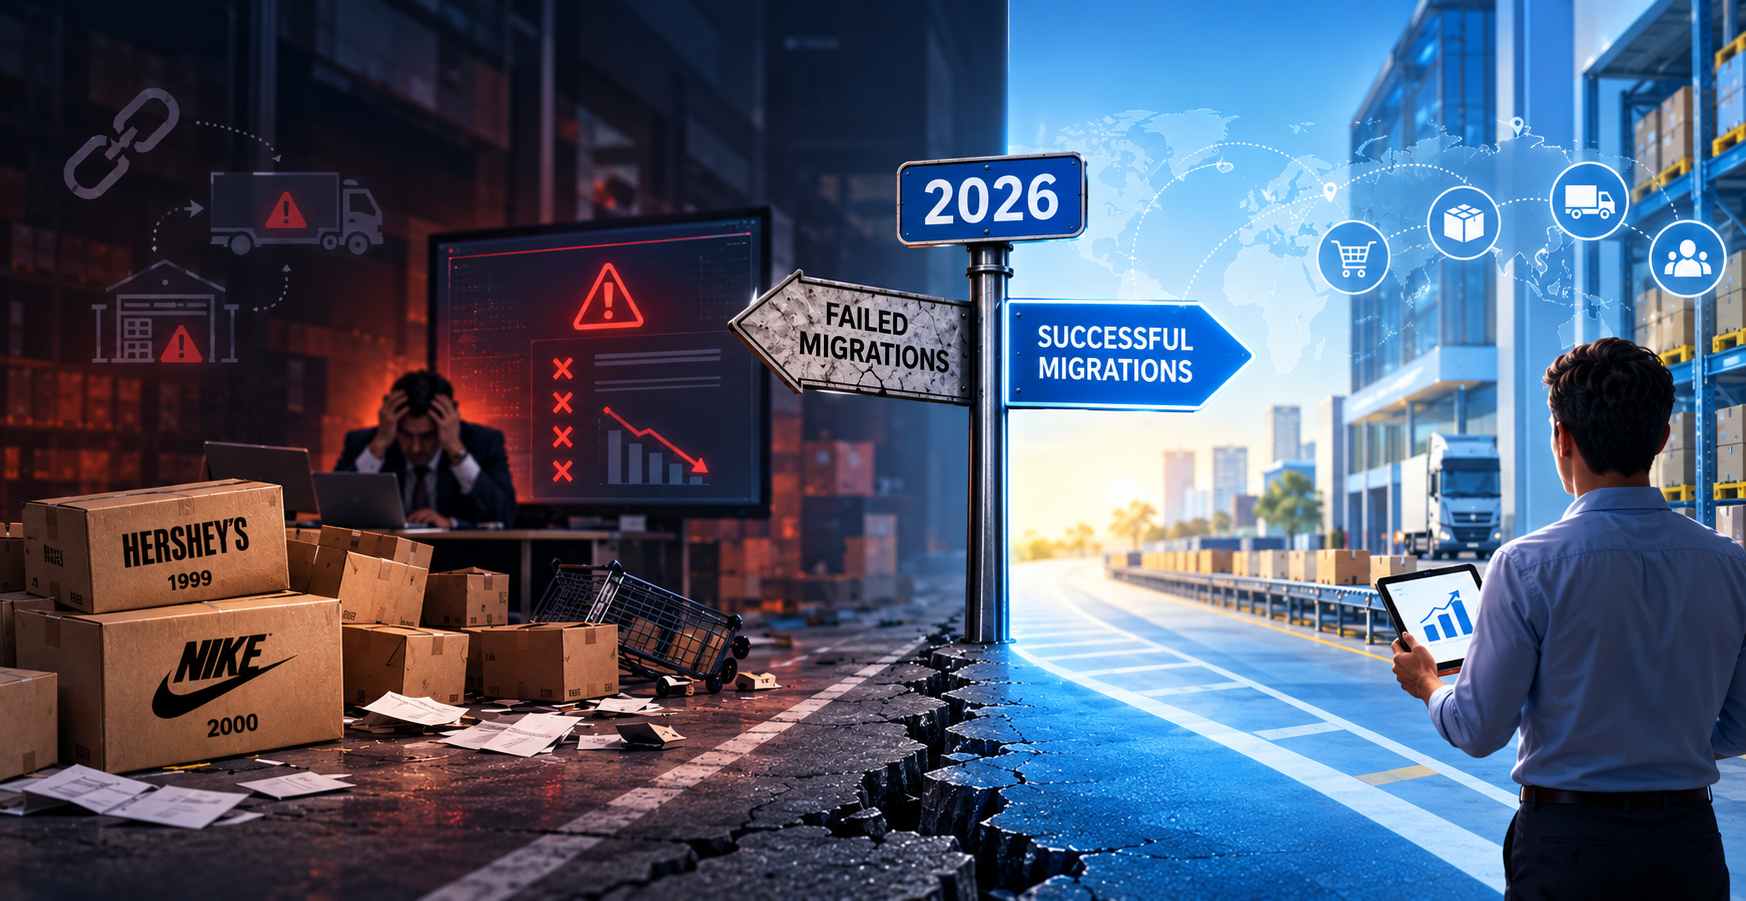
OMS migrations sit in the same failure rate territory as ERP replacements. That is not a comfortable comparison for anyone about to start one. Industry analyses of large ERP and supply chain implementations put the failure rate projects that miss their original business case at 60 70% or higher.
The cautionary tales are named and well documented. Hershey's 1999 go live is the most frequently cited. A big bang cutover rushed in right before the Halloween and Christmas peak broke order fulfilment. It left more than $100M of confirmed orders undelivered despite full warehouses and cut quarterly profit by roughly 19% . Nike's 2000 i2 deployment is the other textbook case. Inadequate testing and over reliance on automated forecasts drove around $100M in lost sales and a ~20% share price drop. Both companies survived and recovered. Many quieter retail OMS misfires since have never made headlines but they still cost the retailers involved months of reconciliation chaos and real customer experience damage during the recovery period.
This piece is not about which vendor to buy. The market is already full of vendor comparison content. If you have landed here after searching for OMS migration risk, you are almost certainly past vendor selection and looking for the checklist you wish someone had handed you before the project started. That is what these covers: why migrations still break in 2026 despite the category being mature, the pre migration diagnostic worth running before you commit to a cutover date, and the phased path that consistently separates the migrations that succeed from the ones that become a war room for months.
What an Order Management System Actually Does (And Why Migrations Are So Risky)
The Six Core Functions of a Modern OMS
A modern OMS orchestrates six things at once: order capture across every sales channel, inventory allocation across every fulfilment node, payment coordination alongside the order lifecycle, fulfilment routing decisions including ship from store and split shipments, returns and refund processing, and customer communication triggered by every status change. These functions do not operate independently. They are deeply interdependent which is precisely why migrating any one of them incorrectly tends to cascade into failures across the others.
Why OMS Sits at the Nervous System Layer of Retail Operations
Every other system in the retail stack depends on the OMS for a consistent, real-time view of what has been ordered, what is in stock, and where it needs to go. That includes the WMS, the ERP, the POS, the payment gateway, and every customer facing channel. When the OMS goes down or produces bad data during a migration, every connected system starts making decisions on incorrect information at the same time. That is a fundamentally different and more dangerous failure mode than a single system going offline in isolation.
What Changed Between First Generation and Distributed OMS
First generation OMS platforms were largely monolithic. They were built for a smaller number of fulfilment paths and lower order complexity. Modern distributed order management platforms handle vastly higher volume. High throughput allocation engines are now capable of up to 500,000 allocation decisions per minute and 675 or more orders per second . They also run more complex fulfilment logic, including ship from store and multi node splitting, and tighter real time integration requirements. All of this means a migration from a first generation system to a modern distributed one is not a like for like technical swap. It is closer to a full re architecture of how orders flow through the business.
The Real Reasons OMS Migrations Still Break in 2026
Reason 1 Under Scoped Integration Inventory (WMS, ERP, POS, Payment)
Teams frequently underestimate how many systems the OMS touches. They discover mid project that a payment gateway integration or a marketplace connector was never properly inventoried at the scoping stage. A planned integration effort then turns into an unplanned scramble discovered well after the timeline and budget were already locked.
Reason 2 Legacy Data Model Assumptions Baked Into Order Records
Years of accumulated legacy order records carry assumptions: specific status codes, custom fields, and workarounds built for edge cases years ago. These often do not map cleanly onto a modern OMS data model. Migrating that data as a literal copy rather than critically examining what those old assumptions actually mean produces order records that look migrated successfully but behave incorrectly. The problem surfaces the first time an edge case triggers logic that no longer matches the old system's behaviour.
Reason 3 Peak Season Cutover Attempts
A legacy enterprise OMS rarely fails outright. It creates ongoing friction that compounds over time, particularly around integration challenges when connecting new ecommerce platforms, POS systems, or third party logistics partners. Attempting a cutover during or immediately before a peak sales period compounds every other risk on this list at once. There is no volume buffer to absorb mistakes and no time to validate before the business genuinely cannot afford downtime or data errors. Hershey's 1999 failure is the definitive example of exactly this mistake.
Reason 4 Fulfilment Logic Migrated as a Copy Instead of a Rebuild
Fulfilment routing rules build up over years through ad hoc exceptions and undocumented tribal knowledge. Teams often treat them as something to replicate exactly, rather than an opportunity to rebuild deliberately. A copied ruleset carries every old inefficiency and edge case workaround forward into the new system frequently without anyone left on the team who remembers why a specific rule exists.
Reason 5 Missing Fallback and Rollback Paths
Some projects commit fully to the new system without a genuine rollback path. That leaves the business with no safe way to reverse course if the cutover reveals a critical issue only after go live. A recoverable problem becomes an extended crisis, simply because there was no planned way back.
Reason 6 Post Cutover Support Model That Assumes Steady State
Support is often staffed for normal, steady state ticket volume. But elevated ticket volume is guaranteed in the days immediately following a cutover. Planning for the wrong baseline leaves the support team overwhelmed exactly when they are least equipped to cope often while still learning the new system themselves.
The Symptoms of an OMS Migration Going Wrong (And How Early You Should Catch Them)
Order Duplication and Missed Order Records
This is among the earliest and most visible symptoms. Duplicate orders get created, or worse orders disappear entirely between systems. Both need to be caught within the first hours of cutover through active reconciliation, not discovered days later through a customer complaint.
Inventory Position Drift Between OMS and WMS
The OMS and WMS gradually start to disagree about what is actually in stock. The symptom often builds slowly and invisibly. It usually continues until oversells start happening at a rate that finally forces attention by which point the drift has been compounding for some time.
Split Shipment Logic Misfiring on Multi Node Fulfilment
Orders that should ship from a single node start splitting unnecessarily across multiple nodes. Or the reverse happens, and orders that need to split are not splitting correctly. Either way, fulfilment cost rises and confusing multi package deliveries generate their own wave of customer service contacts.
Refund and Return Records Not Reconciling to Payment Gateway
Refund records in the new OMS do not match what actually processed at the payment gateway. Finance typically discovers the discrepancy during reconciliation, often weeks after the transactions occurred. By then, tracing the root cause back to the migration is significantly harder than it would have been in real time.
Customer Communication Templates Firing Wrong Status Updates
A customer receives a shipped notification for an order that has not shipped, or a delivered notification for one still in transit. This surfaces immediately and publicly. It generates support contacts and trust damage well out of proportion to what might look like a minor template misconfiguration.
The Pre Migration Diagnostic Every Retail Team Should Run
Run all six checks before committing to a cutover date. Each one exists to surface a specific failure mode while there is still time to fix it cheaply.
Modern implementations that get this diagnostic right report smart automation reducing costs by 10 to 15% while cutting order processing times from days to hours.
The Four Phase OMS Migration Path That Actually Works
Phase 1 Discovery, Data Mapping, and Scope Lockdown
This phase absorbs the pre migration diagnostic work above. It produces a locked scope document that the rest of the project is measured against. That lock is what prevents the scope creep that quietly derails timelines when new integration requirements keep surfacing mid build.
Phase 2 Build, Integration, and Parallel Environment Setup
Build happens in a parallel environment that does not touch live order flow. Every integration point is tested individually first. Then the points are tested together because individually successful tests do not guarantee success when the full system runs simultaneously.
Phase 3 Shadow Mode and Reconciliation Testing
Before cutover, run the new system in shadow mode alongside the live legacy system. The same real order flow runs through both, and the outputs are reconciled. This surfaces discrepancies while the legacy system is still there as the safety net rather than discovering them for the first time after the legacy system has been decommissioned.
Phase 4 Phased Cutover by Channel, Region, or SKU Segment
Do not cut over the entire order flow at once. Migrate by channel, region, or SKU segment in sequence. This contains the blast radius of any issue to a defined, manageable slice of the business, instead of exposing the entire operation simultaneously.
The Operational Side of OMS Migrations Retailers Consistently Under Invest In
Contact Centre Readiness for Post Cutover Ticket Spikes
Ticket volume rises predictably after any cutover. A contact centre staffed and trained on the new system's likely failure modes before go live handles that spike far better than a team learning the system reactively while already underwater on volume.
Back Office Order Reconciliation and Exception Handling
Someone needs to be actively reconciling order records against expected state during the hypercare period. Waiting for automated alerts is not enough. The exceptions that matter most are often exactly the edge cases that automated monitoring was never configured to catch.
Warehouse Ops Training on New Pick Pack Ship Signals
Warehouse staff need hands on training on how the new system's signals differ from the old one before go live not a brief walkthrough the morning of cutover. Pick pack ship errors compound quickly once orders are already moving through a live warehouse floor.
Merchant and Marketplace Communication Plan
Marketplace partners and merchants connected to the OMS need advance notice of the cutover timeline and a clear escalation path for issues. Otherwise they discover the migration happened only when their own order sync suddenly behaves unexpectedly.
Typical enterprise OMS implementation timelines run 8 to 22 weeks depending on scope and integration footprint . That is the window the four phases above need to fit inside without compressing the validation gates that actually prevent failure.
What Good Cutover Weekends Actually Look Like (Hour by Hour)
The cutover itself is a sequence, not a single event. Each phase has a directional target that tells you whether it is safe to proceed to the next.
The Metrics That Tell You an OMS Migration Actually Succeeded
Order Capture Accuracy Rate at T+7 Days
Compare order capture accuracy against the pre migration baseline specifically at the one week mark. Early volume in the first day or two is often lower and less representative than a full week of genuine order flow.
Fulfilment SLA Adherence Compared to Pre Cutover Baseline
Fulfilment speed and accuracy should return to at least pre cutover baseline levels within a defined window. A migration that permanently degrades fulfilment SLA even after stabilisation has not actually succeeded regardless of how smooth the cutover weekend itself felt.
Return and Refund Reconciliation Cycle Time
Track how quickly returns and refunds reconcile against the payment gateway post migration, compared to the pre migration baseline. This is one of the slower surfacing symptoms of a migration that looked clean on the surface but has underlying data issues.
Contact Centre Ticket Volume and Recontact Rate
A genuinely successful migration shows ticket volume returning to baseline within the expected hypercare window. Recontact rate customers having to reach out a second time about the same issue should drop alongside it, rather than staying elevated.
Where 1Point1 Fits in an OMS Migration
The technical build almost always gets the internal focus. The operational side contact centre readiness, back-office reconciliation, and warehouse training is the workstream that most often gets deprioritised, because internal teams are already stretched thin on the migration itself. That is precisely the gap 1Point1 is built to absorb.
1Point1 runs the operational side of enterprise cutovers across e-commerce and retail, BFSI, telecom and media, healthcare, and travel and hospitality the sectors where order and case volume is high and a botched migration is immediately visible to customers. Our role in an OMS migration covers three specific workstreams:
- Contact centre hypercare staffing. We staff and train agents on the new system's likely failure modes before go live wrong status notifications, split shipment confusion, refund queries so the post cutover ticket spike is absorbed by a prepared team, not a reactive one.
- Back office reconciliation through hypercare. We run active, human led reconciliation of order records against expected state during the T+6 to T+72 window and beyond, catching the edge case exceptions that automated monitoring is not configured to see.
- Warehouse training coordination. We help align warehouse teams on the new pick pack ship signals ahead of cutover, so errors do not compound on a live floor.
Across these engagements, retailers typically target [ticket volume returning to baseline within the hypercare window], [recontact rate held at or below pre migration levels], and [reconciliation cycle time restored to baseline] replace these bracketed placeholders with the actual anonymised metrics from your own cutover engagements before publishing.
The result is that the operational side gets resourced as seriously as the technical build which is the single most reliable difference between a migration that is technically successful and one that is also customer experience successful.
Conclusion
OMS migrations do not fail because the technology is immature or because good vendors do not exist. They fail because the operational and data complexity underneath a retailer's current order flow gets consistently underestimated at the scoping stage. And they fail because the cutover gets treated as a single event rather than a phased process with genuine validation gates along the way. The retailers who get through a migration cleanly are not the ones with the biggest budget. They are the ones who ran the pre migration diagnostic honestly, built in a real rollback path, and resourced the operational side contact centre, back-office reconciliation, and warehouse training as seriously as the technical build itself.
If your retail team is planning an OMS migration and needs the operational side resourced properly contact centre readiness, back-office reconciliation, and hypercare support 1Point1 has run this playbook across enterprise retail cutovers.
Visit https://www.1point1.com/ to talk to our team.